> ## Documentation Index
> Fetch the complete documentation index at: https://docs.weaveos.com/llms.txt
> Use this file to discover all available pages before exploring further.
# Benchmarks
> Compare your team's performance against similar organizations, by size or by industry
Weave benchmarks compare your engineering and AI metrics, including AI tool costs, AI cost per AI output, and AI output percentage, with other organizations that use Weave. By default you're compared with organizations that have a similar number of engineers; an admin can switch the comparison to organizations in your industry, and internal lines show your own organization's average and median. Benchmarks appear as reference lines on charts and as percentile ranks.
## What are benchmarks?
Benchmarks let you compare your team's performance against other engineering organizations. Weave calculates them from real data from the organizations that use the product, grouped into peer populations so the comparison is meaningful.
You choose which population you are measured against: organizations of a **similar size**, organizations in **your industry**, or the rest of **your own organization**.
## How to configure benchmarks
In the top right corner of any page, click the settings icon to configure your benchmarks.
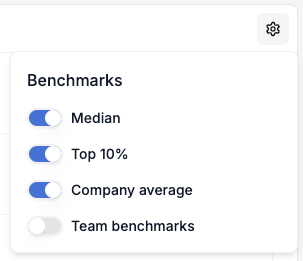 Which lines appear on charts is set under **Benchmarks**. Which population you are compared against is set under **Annotations**, applies to your whole organization, and can only be changed by an organization admin.
## Peer groups
### Organization size
The default. Most benchmarks are calculated separately for each size band, since team dynamics and performance characteristics vary significantly between small startups and large enterprises. A few metrics are compared against all organizations instead — see [metric coverage](#metric-coverage).
| Bucket | Description |
| - | - |
| **1-5 engineers** | Small teams and startups |
| **6-10 engineers** | Growing startups |
| **11-20 engineers** | Mid-size teams |
| **21-50 engineers** | Established companies |
| **51-100 engineers** | Large teams |
| **101-200 engineers** | Enterprise teams |
| **201+ engineers** | Large enterprises |
Your organization is automatically placed in the appropriate bucket based on the number of engineers with at least one team membership.
### Within your organization
Compare each person against the rest of your own organization rather than against other companies. Useful when your organization is unusual enough that external comparison is not the question you are asking.
### Industry
Opt in under **Annotations** to be compared against organizations in the same industry instead, at any size. A 30-engineer fintech is measured against other fintechs rather than against every 21-50 engineer organization.
Weave assigns your industry automatically from your organization's public profile. The two axes are alternatives, not a combination: an industry benchmark spans every size band.
| Industry | Covers |
| - | - |
| **Fintech** | Financial services, payments, banking, lending, insurance, trading, crypto, accounting |
| **Healthtech** | Healthcare, clinical care, medical records, pharma, health insurance, wellness, life sciences |
| **Developer tools** | Developer tools, data infrastructure, AI/ML infrastructure, cloud, observability, IT ops |
| **Security** | Security, identity, fraud, privacy, governance, risk and compliance |
| **Martech** | Marketing, advertising, sales tech, CRM, customer engagement, revenue intelligence |
| **HR** | HR, payroll, recruiting, talent, workforce management, employee benefits |
| **Logistics** | Logistics, freight, transport, supply chain, procurement, warehousing, trade, distribution |
| **Retail** | Retail, e-commerce, marketplaces, consumer goods, food and grocery, direct-to-consumer |
| **Hospitality** | Hotels, short-term rentals, restaurants, travel, attractions, ticketing, venues, events |
| **Edtech** | Education, schools, universities, training, research |
| **Media** | Media, gaming, entertainment, sports, publishing, video, social |
| **IT services** | IT services, consulting, custom software agencies, staffing, outsourced engineering |
| **Real estate** | Real estate, property management, construction, proptech, facilities |
| **Govtech** | Government, public sector, defense, civic, regulatory compliance for public bodies |
| **Industrial** | Manufacturing, energy, utilities, agriculture, hardware, industrial IoT |
| **Legal** | Legal technology: contract review, litigation, patents, e-discovery, law-firm software |
Organizations whose software sells across every vertical are tagged **horizontal** and stay on the size axis. Their metrics are statistically indistinguishable from the population as a whole, so an industry line would carry no extra signal.
### Privacy floor
An industry benchmark is only published when the peer group is large enough that no single organization can be identified from it:
* At least **5 organizations** in the industry, and
* Each contributing organization has at least **10 engineers**
Below that threshold the industry distribution is suppressed and not stored at all.
Suppression is per metric, not per industry. If your industry has enough peers
for code output but not for code review quality, the first is an industry
comparison and the second falls back to your size bucket. Every percentile and
benchmark line in the product names the population it was actually calculated
over, so the two are never presented as the same thing.
Open-source organizations are excluded from the industry axis in both directions — they neither contribute to nor read an industry distribution — because their contribution patterns differ enough to distort a commercial peer group.
## Benchmark types
### Percentile benchmarks
Percentile benchmarks show how your metrics compare to your peer group:
* **Median (50th percentile)**: The middle value - half of organizations perform better, half perform worse
* **Top 10% (90th percentile)**: High-performing organizations - only 10% of organizations perform better
* **Top 1% (99th percentile)**: The strongest organizations in the peer group
These appear as reference lines on time-series charts. Hover any line to see which population it was calculated over.
**Percentile rank** is a score from 0-100 showing where your performance ranks. For example, a rank of 85 means you're performing better than 85% of your peer group. Higher percentile ranks always indicate better performance - for metrics where lower values are better (like code review turnaround), the rank is automatically inverted.
### Organizational benchmarks
These benchmarks compare your performance to other reference points inside your own organization, and are unaffected by your peer group setting:
* **Company average**: Your organization's overall average performance
* **Company median**: The median across engineers in your organization (less skewed by top performers than the average)
* **Team average**: Your team's average performance (when available)
Note: on an [individual report page](/reports/individual), that individual's contributions will be excluded from the team average if they are on the team.
## Metric coverage
Most benchmarked metrics are calculated per size bucket, and most of those also have an industry comparison. Four metrics do not yet have enough data to segment meaningfully, so they are compared against **all organizations at once** rather than against a size or industry peer group.
| Metric | Peer group | Industry |
| - | - | - |
| Code output per engineer | Size bucket | Yes |
| PRs per engineer | Size bucket | Yes |
| AI-assisted LOC | Size bucket | Yes |
| AI code percentage | Size bucket | Yes |
| AI output percentage | Size bucket | Yes |
| Code review quality | Size bucket | Yes |
| Code review turnaround | Size bucket | Yes |
| Review cycles | Size bucket | Yes |
| Comment resolution rate | Size bucket | Yes |
| PR cycle time | Size bucket | Yes |
| Code LOC turnover | Size bucket | Yes |
| Innovation ratio | Size bucket | Yes |
| Bug ratio | Size bucket | Yes |
| Bugs introduced | Size bucket | Yes |
| Reverted PRs | Size bucket | Yes |
| AI tool costs | Size bucket | Yes |
| AI cost per AI output | Size bucket | Yes |
| Output per AI dollar | Size bucket | Yes |
| AI code output | All organizations | No |
| AI token usage | All organizations | No |
| AI code turnover | All organizations | No |
| Conversation prompt quality | All organizations | No |
A metric with no industry row falls back to its size comparison, and says so. The four all-organization metrics are unaffected by your peer group setting.
## How benchmarks are calculated
### Data collection
* **Time period**: 180 days of historical data
* **Refresh**: recalculated on the 1st and 15th of each month
* **Data sources**: Real metrics from engineering organizations using Weave
* **Filtering**: Only includes non-generated (human-written) code and PRs
### Scaling by context
Benchmark values are automatically scaled based on how you're viewing the data:
* **Individual/Account view**: Shows per-person benchmarks
* **Team view**: Scales benchmarks by average team size
* **Organization view**: Scales benchmarks by total organization size
For metrics that accumulate over time, values are normalized to per-day rates to ensure fair comparisons regardless of the time period analyzed.
## Common questions
### Can I benchmark AI cost per output against similar companies?
Yes. AI tool costs, AI cost per AI output, and output per AI dollar are benchmarked at the organization level against your size bucket, or against your industry if an admin selects it. On the [AI report](/reports/ai), the **Cost per output over time** chart can show these benchmark lines and your percentile rank.
### Which companies am I compared with?
Other organizations that use Weave, grouped by number of engineers or by industry. Benchmarks are percentiles of the group (median, top 10%, and top 1%), and an industry benchmark is only published when at least 5 organizations with 10 or more engineers each contribute to it.
### Which AI metrics have benchmarks?
AI-assisted lines of code (LOC), AI code percentage, AI output percentage, AI tool costs, AI cost per AI output, and output per AI dollar are compared within your size bucket or industry. AI code output, AI token usage, AI code turnover, and [conversation prompt quality](/metrics/conversation-prompt-quality) are compared with all organizations, because there isn't enough data yet to split them.
### Can I compare against my own organization instead?
Yes. An admin can set **Compare against** to **Within your org** under **Annotations**. The **Company average** and **Company median** lines under **Benchmarks** also use only your organization's data, whichever peer group is selected.
### How often are benchmarks updated?
Weave recalculates them on the 1st and 15th of each month from the previous 180 days of data.
This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.